Category Archives: Software Development

Dev Stack, Part XIII: Local AI

This is the latest post documenting my tech stack built around using coding agents safely. The previous posts were:

Up until this past week, I had been using cloud based AI, but the endgame of this setup was to get onto local AI. In Part II, I mentioned that I moved to Linux on a Framework Desktop. That machine is using an AMD Ryzen AI Max+ with 64GB of unified memory. This is definitely good enough to run some interesting local models, but I do regret not getting a 128GB back in December when I bought it. When prices come down again, I will be upgrading.

For hosting models, I use Ollama. I tried a bunch of models. For each one, I gave it a simple command as a way to “eval” it: “Build and run nebulas tests”. I’ll explain more in the next post when I write about my coding agent (Pi.dev). Of the ones I tried, only qwen3-coder-next could do this without more help.

Here are some random technical notes about the setup:

  • For a Framework, everything you need to know is documented well this AMD Playbook about Ollama.
  • The main difference between an AMD setup and others is how you allocate memory to the GPU. A Ryzen uses Unified memory (shared between the CPU and CPU), which is similar to how the Apple M series chips work. In the playbook, it explains how to do that. I decided to set the minimum to 512k via the BIOS and then used amd-ttm to set the shared memory pool to 48GB for now.
  • With the above setup and the qwen-coder-next model, I get 93% of the model running on the GPU and 7% on the CPU. This is tolerable, but it would be better to be at 100%.
  • However, I am getting 36 tokens/sec which is more than fast enough.

In the next post, I’ll explain how I sandbox Pi in the Docker and connect it to Ollama.
Dev Stack, Part XII: Sandboxing Update (Docker)

Late last year, I completely changed my dev stack to Python on Linux with some other things. I wrote a series about it at the time:

In Part XI, I described using KVM (a full virtualized VM) and specifically not Docker. At the time, I wrote:

Docker: I am not that comfortable with it, and it seems like running GUIs (like VSCode) is not trivial. It would be more efficient with sharing installed software, but wasting disk space is just not an issue.

After using a VM for several months, I have decided to bite the bullet and learn Docker more and get comfortable with it. I’m not trying to run VSCode in it, just terminal based coding agents (which I will describe in a future post).

My setup is simple. I started with a Dockerfile based on node because I wanted to use Pi.dev and that is installed via npm. I gave it the minimal tools needed to build my project (a game built with C and Raylib), which is just gcc, X11, OpenGL, and a few other things.

To harden the security, I created a docker private network and put the Docker into that network. From there it has no internet or network access at all. I opened up one port so that the Docker could talk to Ollama on my host machine.

In the next post of this series, I’ll elaborate on the entire local AI and Pi.dev setup.

Limiting the Chance of Code Agent Prompt Injections

Yesterday, I wrote about the Lethal Trifecta when using coding agents and how I am escaping it via sandboxing. I built a place to code where there is nothing valuable to lose. The agents might be poisoned by prompt injection and able to phone home, but there’s nothing to send. I can wipe the entire VM at any time and rebuild it from a snapshot or from scratch easily.

This deals with one leg of the trifecta, which is sufficient, but I don’t ignore the other two.

To limit the chance of an agent being exposed to a prompt injections, I build on an architecture of very limited dependencies. My current project is to build visualizations in JS on D3. I only include D3 on pages in the browser (it’s not on my machine). I don’t use npm, and I have no other dependencies.

The thing I miss most is jest, but I decided to build a minimal testing framework (just need to run functions and make assertions). I run the tests in a browser, so I get access to a DOM too, which I could test against. All of the code for this project only makes sense inside of a web page in the browser, which is another sandbox. It’s like Inception up in here.

My other projects are python based and live in their own VM. I need some dependencies there (pandas, numpy, matplotlib and more). The main thing I am doing is keeping that separate from the visualization project so that any issue in one doesn’t affect the other.

Nothing else that I need for the project (that I didn’t create) lives in that VM.

My main exposure to untrusted text is that I let the agent browse the web. I don’t see how I could avoid this, which is why this leg of the trifecta could never be the one I eliminate.

Escaping the Lethal Trifecta of AI Agents

The “Lethal Trifecta” is a term coined by Simon Willison that posits that you are open to an attacker stealing your data using your own AI agent if that agent has:

You need all three to be vulnerable, but usage of Claw or Coding agents will have them by default. I would say that the second two are almost impossible to stop.

#2 Untrusted content includes all of your incoming email and messages, all documents you didn’t write, all packages you have downloaded (via pip, npm, or whatever) and every web page you let the agent read. I have no idea how to make an agent useful without some of these (especially web searching).

#3 External communication includes any API call you let it make, embedded images in responses, or just letting it read the web. Even if you whitelist domains, agents have found ways to piggyback communication because many URLs/APIs have a way of embedding a follow-up URL inside of them.

For my uses, I find it impossible to avoid these two. Reduce? Yes, but not eliminate.

So, my only chance to escape the trifecta is to not give agents access to my private data. This means that I would never let an agent process my email or messages. I also would never run them on my personal laptop. I would never let them login as me to a service.

This is why I built hardware and software sandboxes to code in. Inside a VM on a dedicated machine, there is no private data at all. I use it while assuming that all code inside that VM is untrusted and that my agent is compromised. I do my best to try to make sure that won’t happen, but my main concern is that there is no harm if it does happen.

Incidentally, this same lethal trifecta also applies to every package you install into your coding projects. If an NPM package can (1) read your secrets (2) is untrusted and (3) can communicate, then you may suffer from a supply chain attack. It’s obvious that code you install and run makes #2 and #3 impossible to safeguard against. Not having secrets in the VM is the best solution for supply chain attacks too.

Tomorrow, I’ll follow up with how I reduce the other two legs of the lethal trifecta.

Dev Stack, Part XI: Sandboxing

Update: I have since changed my mind and moved to Docker.

Late last year, I completely changed my dev stack to Python on Linux with some other things. I wrote a series about it at the time:

My choices were driven by the dangers of AI Coding Agents and Supply Chain attacks (more generally, just running untrusted code).

Getting all development off of my main machine was a big step. Choosing Linux for that machine was driven by cost per computing power for a desktop machine, and that I only need to run VSCode, a browser, and dev tools that are Linux first anyway.

I have been programming on the bare OS, but I was always going to want more isolation between projects and between the projects and the machine. I finally completed that step.

My choice was to use QEMU-KVM, an open-source VM solution. This blog about QEMU-KVM on Ubuntu was the most useful (and accurate) for me.

My general setup:

  1. The machine only has Ubuntu, Firefox, Tailscale (see networking), and my KVM setup described above.
  2. I built one VM to work on a new project (charting visualizations for Google Sheets), which only needs Ubuntu, VSCode, Git, and Firefox.
  3. This project is in Javascript, but I am building it with a dependency on D3 and nothing else. No NPM, not even jest. D3 is only loaded by the browser (not on the machine)
  4. For testing, I am building a minimal test harness in JS. It runs in the browser, so it will also be able to do DOM testing.
  5. There is no firewall yet, but I will probably do that soon. As a first step, just limiting the ports. I will document that if I go that way. It would be inside the VM.
  6. I allow some limited logged in browsing in my outside OS, mostly ChatGPT, but not Google. The main OS is for research. Nothing else can be installed on it (through any means, even trusted). The VM browsers are only for using my software (not the internet).

Other solutions I considered:

  1. Cloud based programming (like codespaces): This would definitely work for some projects I have, but I feel like I’d run up against limitations. Long-term, I think this will become the only sane way to program.
  2. Docker: I am not that comfortable with it, and it seems like running GUIs (like VSCode) is not trivial. It would be more efficient with sharing installed software, but wasting disk space is just not an issue.
  3. No Sandbox: Just putting all development on a dedicated computer is probably enough. I went the VM route mostly out of personal interest. Having done it, one big plus is snapshotting.

Finding My First Open Source Contribution

I keep track of my GitHub open source contributions on this site’s GitHub page, but only back to 2013. According to GitHub, I opened my account in late 2010 to open a couple of issues on Yammer.net, which I was using to build an internal tool for Atalasoft that needed access to our Yammer data (Yammer was a precursor to Slack).

My first GitHub source contribution was to YUICompressor (a JavaScript compression tool) to output a Munge Map to aid debugging. I PR’d it in 2011. I needed this to help debug Atalasoft’s JS code in production.

But, that’s just GitHub. I’ve been posting code in other places before that. Here’s a multithreaded prime number sieve in clojure from 2008. Here’s a port of Apple’s CPPUnit to run on Windows from 2006. I found evidence that I published a JavaScript Code39 Bar Code Generator on my Atalasoft blog in 2008, which also has a Code39 web app based on it (which hosts the JS code). I have a lot of code snippets on StackOverflow, but only after 2008. My first post with code was in 2003 (comparing jUnit and NUnit).

I had a distinct memory of emailing an open source dev with a multi-threaded race condition fix for a C++ data structure that we used at Spheresoft. Looking at a list of our external libraries jarred my memory that it was WFC by Samuel R. Blackburn. I also found the WFC release notes in the Wayback Machine that mention my fix. He migrated WFC to GitHub much later, but I found a comment mentioning my fix. The actual diff predates the migration, but it’s the double-checked locking directly below the comment:

    // 1999-12-08
    // Many many thanks go to Lou Franco (lfranco@spheresoft.com)
    // for finding an bug here. In rare but recreatable situations,
    // m_AddIndex could be in an invalid state.

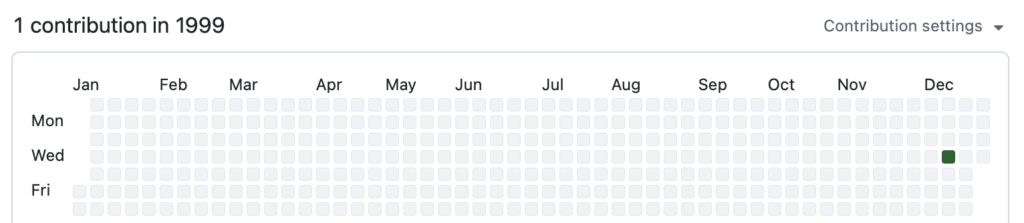
So, that’s 1999. Ironically, my oldest verified contribution is actually on GitHub, but predates its release by about eight years. Where’s my green square?

Before that, I have to go by memory because I can’t find the originals.

One thing that came to mind was back in college. I co-developed code for our computer center to draw plots on a Unix PC terminal (saving paper). Using that code, we also built a Unix PC driver for GNU Plot and sent it to them. I am pretty sure this was hosted on MIT’s Athena.

That would be in 1991 or so. I did some simple searches and didn’t find it, but supposedly there are FTP archives from that era, so I might try looking later.

Re-Onboarding Via Tech Debt Payments

I just opened a project I haven’t looked at in a few weeks because “holidays”. First thing I did was run tests, which didn’t run because I didn’t run them correctly. I looked at the README and it had no documentation for running tests.

In my book, Swimming in Tech Debt, I talk about this in the opening of “Chapter 8: Start with Tech Debt”. You can read this sample chapter and others by signing up to my list:

It opens:

You know the feeling. You sit down at your computer, ready to work on a feature story that you think will be fun. You sort of know what to do, and you know the area of code you need to change. You’re confident in your estimate that you can get it done today, and you’re looking forward to doing it.

You bring up the file, start reading … and then your heart sinks. “I don’t get how this works” or “this looks risky to change,” you think. You worry that if you make the changes that you think will work, you’ll break something else.

What you are feeling is resistance, which triggers you to procrastinate. You might do something semi-productive, like reading more code. Or you might ask for help (which is fine, but now you’ll need to wait). Maybe you reflexively go check Slack or email. Or worse, you might be so frustrated that you seek out an even less productive distraction.

The chapter is about immediately addressing this debt because you know it is affecting your productivity. It’s essentially free to do something now rather than working with the resistance.

So, following my own advice:

  1. I added text to the README explaining the project dev environment and how to run tests and get coverage data.
  2. Seeing the coverage data, I saw a file with 0 coverage and immediately prompted Copilot to write a test for one of the functions in it.

And that was enough to get warmed up to start doing what I was originally trying to do.

LLMs Are Good At (some) Languages

Yesterday, I wrote about how I am going to use Page-o-Mat to make some Supernote page templates. Page-o-Mat is a python program that lets you describe journals using a YAML based configuration and then generates a PDF. Since template pages are just a PDF, you can use Page-o-Mat for that too.

My first step was to see if I could get ChatGPT to help me. At first, I gave it a link to the docs, but it seemed to have trouble accessing it. So, I just grabbed the YAML for my 2025 journal and pasted it in the chat. Then, I asked what kind of template pages I should make. Its ideas were pretty good and it generated some for me, which worked great.

But, then I asked if it could just make the PDF directly—which it did. On inspection, I see the PDF was generated by https://www.reportlab.com, which says that their “flagship commercial tool for making beautiful PDFs quickly using Report Markup Language and a preprocessor. Create PDFs the same way you create dynamic web pages”. So, it’s essentially (like Page-o-Mat) a language for generating PDFs.

It’s interesting that ChatGPT makes PDF with a language tool even though PDFs themselves are a language. Knowing the internals of PDF, it makes sense. You need to remember the exact byte locations of each object you create to write out the PDF trailer at the end. It’s extremely easy to mess up and there isn’t a good tool for debugging it. Humans would be horrible at making it by hand, and so are LLMs (but we both can make PDFs with tools).

Protecting Myself

I was recently on the Scrum Master Toolbox podcast with Vasco Duarte in a series about AI assisted coding. In it, I said that I read every line of AI generated code (and fix it, if necessary) before I commit it.

This isn’t exactly right.

I read all code, even my own, and fix it before I commit. Doing it for AI is just an extension of how I normally work. I do this for my code because I often find problems. This is even more true for AI generated code.

Another reason to do this is because it makes code go through code review and testing faster. I have written about that previously:

Now that I am the only programmer on my project, I don’t need to worry about code review, but I do have to worry about DevOps, and frankly, I am not willing to trust AI to write code that I have to run. I have already fixed code that introduced beginner level security problems, so pure Vibe Coding on a project meant to be used by others on the web is not an option for me.

Dependency Maintenance vs. Supply Chain Attacks

I am assuming that you basically know what a supply chain attack is, but briefly, it’s when the code you install as a dependency in your development project contains malware. Unfortunately, all dependencies are code, and this code is usually run at a high privilege without needing to be signed.

The main thing it will try to do is grab keys and secrets from your .env files or environment variables and exfiltrate them. Some are targeted at blockchain developers and will try to steal their coins.

This is not a comprehensive guide. I am documenting my decisions based on my needs.

Like William Woodruff, I agree that We Should All Be Using Dependency Cooldowns. TL;DR is in the title. Essentially, never install a dependency that isn’t at least a few days old. The downside is defense against 0-day security fixes. If this is an issue, you could take the time to investigate and adopt the fix with an override.

The other broad advice with little downside is to not allow install scripts to run. You might still install malware, but if you let the install scripts run, they own you immediately. But since you are likely about to run the code inside your project, it’s not much protection. I do it anyway. The downside is when a dependency needs its post-install script to work. I used can-i-ignore-scripts to check for this issue when I used npm.

Ultimately, though, I have decided to leave the npm ecosystem and stop using node and React. Other ecosystems can have supply chain problems, but npm is having them on a regular basis because they are a prime target, and their practices have not scaled enough to deal with this.

I have also left Cursor and gone back to VSCode because Cursor’s fork cannot install the latest version of VSCode extensions. Extensions are also part of the supply chain and can be either malware or a hacking vector, so not being able to update them is not an option for me.

My next decision was to build a dedicated machine for software development. This machine does not have my personal data or information on it. It is not logged into any personal service (like my email). I have not yet dockerized all of my dev environments on it, but that’s a likely next step.

I also limit my dependencies. Another benefit of leaving the JS ecosystem is that Python isn’t as reliant on so many tiny dependencies. I was shocked at how many dependencies React, TypeScript and node/Express installed (I counted 10s of thousands of files in node_modules), and this is before you have written one line of application code. I like the batteries-included ethos of Django and Python. Most of what I need is built-in.

I have written a lot about dependencies and how it’s tech debt the moment you install it.

My final defense against supply chain problems is to have a regular dependency updating policy. Of course, this needs to be done with a cooldown, but my main reason to do it is because ignoring dependencies makes it very hard to do something about problems in the future. The more out of date you are, the harder everything is. Regular updating will also remind you of how bad it is to have dependencies.

To make this palatable, I timebox it. It really should take less than an hour for my project. Even at Trello, it only took a few hours to update the iOS project, which we did every three weeks. You also need extensive, automated test suites and time to test manually.

If updating takes longer for some reason, then the dependency that is causing this is now suspect. I will probably plan to remove it. If I need it (like Django), then I consider this a dry-run for a project I need to plan.